import numpy as np

rng = np.random.default_rng(137)10 NumPy Random Numbers
(CSE331) Python for Data Science
NumPy can draw random samples from a collection and generate values from probability distributions. We will use these tools for sampling and estimating probabilities by simulation.
rng is a random-number generator. The seed makes the sequence reproducible when the same code is run in the same order in the same software setup.
To generate fresh random results each time you run the code, omit the seed:
rng = np.random.default_rng()Both versions generate pseudorandom numbers. Setting a seed makes the sequence reproducible; omitting it lets NumPy initialize the generator using entropy from the operating system.
In this lecture, we use rng = np.random.default_rng(137) for reproducibility. Set it once at the beginning: successive draws advance the sequence, while restarting with the same seed and running the same code in the same order reproduces the results.
1 Random Sampling
Use choice() to select values from a one-dimensional collection:
rng.choice(a, size=None, replace=True, p=None)| Argument | Meaning |
|---|---|
a |
Collection of possible outcomes |
size |
Number of draws; omitted or None returns one scalar |
replace |
True allows repeated selection; False samples without replacement |
p |
Probability for each outcome; omitted means equal probabilities |
1.1 Rolling a fair die
faces = np.arange(1, 7)
print(rng.choice(faces))          # one scalar value
print(rng.choice(faces, size=1))  # array containing one value
print(rng.choice(faces, size=8))  # eight rolls
3
[6]
[2 2 6 3 2 4 4 3]Sampling with replacement allows the same face to appear on several rolls.
1.2 Rolling a loaded die
Probabilities must be nonnegative, sum to 1, and correspond to the outcomes in the same order.
probabilities = [0.5, 0.2, 0.1, 0.1, 0.05, 0.05]
loaded_rolls = rng.choice(faces, size=10, p=probabilities)
print(loaded_rolls)
[1 2 1 1 1 4 4 3 2 1]Here face 1 has probability 0.5. This does not require exactly half of a small sample to be 1.
1.3 Sampling labels
labels = rng.choice(["A", "B", "C"], size=10)
print(labels)
['B' 'B' 'A' 'C' 'C' 'A' 'B' 'C' 'A' 'B']1.4 Sampling without replacement
names = ["Anna", "Beth", "Chad", "Drew", "Emma",
         "Fred", "Gary", "Hana", "Iris", "Jake"]
group = rng.choice(names, size=5, replace=False)
print(group)
['Jake' 'Fred' 'Iris' 'Gary' 'Emma']Each entry can be selected at most once, and the sample size cannot exceed the number of available entries. Use unique names or IDs when sampling people: duplicated labels in the source can still appear in the result.
2 Sampling from Distributions
We focus on the uniform, normal, and gamma distributions. The size argument specifies how many values to generate.
2.1 Uniform distribution
For a continuous uniform distribution on an interval, equal-length subintervals have equal probability. The density is constant; the probability at any one exact point is zero.
unif_sample = rng.uniform(low=6, high=10, size=10000)
print(unif_sample[:10])
[9.14329841 6.12648352 6.03017422 9.91325067 6.28105084 6.5717998
7.95198271 7.67859813 9.91214425 8.96957353]The sampling interval is nominally [6, 10): the upper endpoint is excluded, apart from possible floating-point rounding. Its theoretical density is \(1/(10-6)=0.25\).
Code
import matplotlib.pyplot as plt

plt.figure(figsize=(4, 3))
plt.hist(unif_sample, bins=np.linspace(6, 10, 21),
         density=True, edgecolor="black")
plt.xlabel("Sampled value")
plt.ylabel("Density")
plt.title("Uniform(6, 10)")
plt.tight_layout()
plt.show()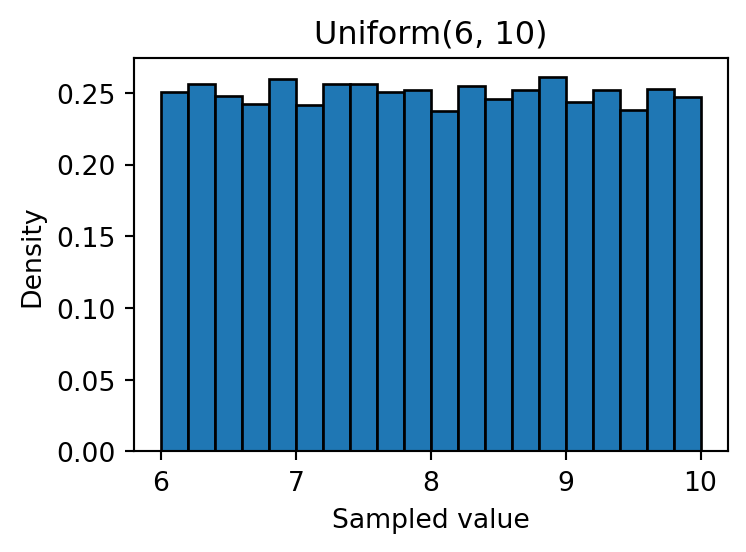
With density=True, the total bar area is 1. The heights are densities, not proportions. Small differences between bars are expected in a random sample.
2.2 Normal distribution
For a normal distribution, loc is the mean \(\mu\) and scale is the standard deviation \(\sigma\), not the variance.
norm_sample = rng.normal(loc=10, scale=3, size=10000)
print(norm_sample[:10])
[ 7.19415751 10.42294794 12.19011096 6.06576486 9.61579153 4.40917236
11.47689585 13.57861992 8.88475934 14.24580362]Code
plt.figure(figsize=(4, 3))
plt.hist(norm_sample, bins=30, density=True, edgecolor="black")
plt.xlabel("Sampled value")
plt.ylabel("Density")
plt.title("Normal: mean 10, SD 3")
plt.tight_layout()
plt.show()
The sample histogram should be roughly bell-shaped. The sampled mean and standard deviation will be close to, but generally not exactly, the specified values.
Estimating probabilities by simulation
For this example, use a normal distribution with mean 10 and SD 2.
X = rng.normal(loc=10, scale=2, size=100000)

print("P(X < 10):", np.mean(X < 10))
print("P(X < 12):", np.mean(X < 12))
print("P(8 < X < 12):", np.mean((X > 8) & (X < 12)))
print("P(6 < X < 14):", np.mean((X > 6) & (X < 14)))
print("P(4 < X < 16):", np.mean((X > 4) & (X < 16)))
P(X < 10): 0.50197
P(X < 12): 0.8412
P(8 < X < 12): 0.68137
P(6 < X < 14): 0.95425
P(4 < X < 16): 0.99738X < 10 creates a Boolean array. Its mean is the proportion of simulated values below 10, which estimates the probability.
The results should be near 0.5000, 0.8413, 0.6827, 0.9545, and 0.9973, respectively. A larger sample generally improves precision, but simulation does not give an exact probability.
2.3 Gamma distribution
A gamma random variable takes positive values and is right-skewed. It can model positive quantities such as waiting times when its assumptions are suitable.
NumPy uses shape \(k\) and scale \(\theta\). If a formula instead uses a rate \(\lambda\), then \(\theta=1/\lambda\).
gamma_sample = rng.gamma(shape=3, scale=10, size=10000)
print(gamma_sample[:10])
[37.16215344 38.47103908 14.54354218 26.88800845 18.40283242 15.4166886
35.978082 17.92350765 26.53076925 12.45014884]For this parameterization, the mean is \(k\theta=30\) and the variance is \(k\theta^2=300\).
Code
plt.figure(figsize=(4, 3))
plt.hist(gamma_sample, bins=30, density=True, edgecolor="black")
plt.xlabel("Sampled value")
plt.ylabel("Density")
plt.title("Gamma: shape 3, scale 10")
plt.tight_layout()
plt.show()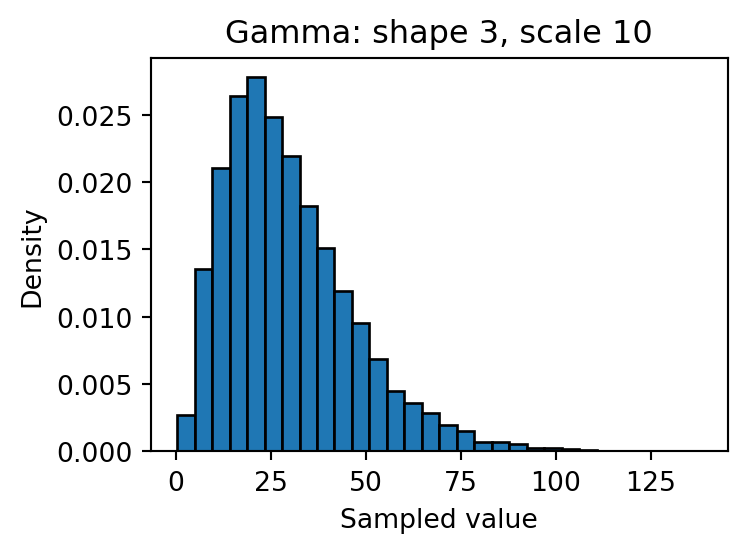
3 Other Distribution Methods: Reference
These methods are available on rng; this lecture’s worked examples focus on the three distributions above.
| Method | Generates |
|---|---|
rng.uniform() |
Uniform values |
rng.integers() |
Integers from low up to but excluding high by default |
rng.standard_normal() |
Normal values with mean 0 and SD 1 |
rng.binomial() |
Binomial counts |
rng.normal() |
Normal values with specified mean and SD |
rng.beta() |
Beta values |
rng.chisquare() |
Chi-square values |
rng.gamma() |
Gamma values |
4 Exercises
- Roll a fair die 1,000 times using
choice(). Estimate the probability of an even number and compare it with 0.5. - Select four names without replacement from the given list. Explain why requesting 11 names would fail.
- Generate 10,000 observations from Uniform(2, 8). Estimate \(P(X>5)\) and compare it with 0.5.
- Generate 100,000 observations from a normal distribution with mean 50 and SD 5. Estimate \(P(X<45)\) and \(P(45<X<55)\).
- Generate 10,000 gamma observations with shape 2 and scale 4. Compare their mean with the theoretical mean and draw a density histogram using the supplied plotting pattern.
5 Summary
- Create a seeded generator for reproducible examples and run cells in order.
- Use
choice()for sampling with or without replacement. - Check parameter meanings, especially normal SD and gamma scale.
- Estimate probabilities as proportions of simulated values meeting a condition.